Engineering notes on distributed inference
Latest blog posts
Research
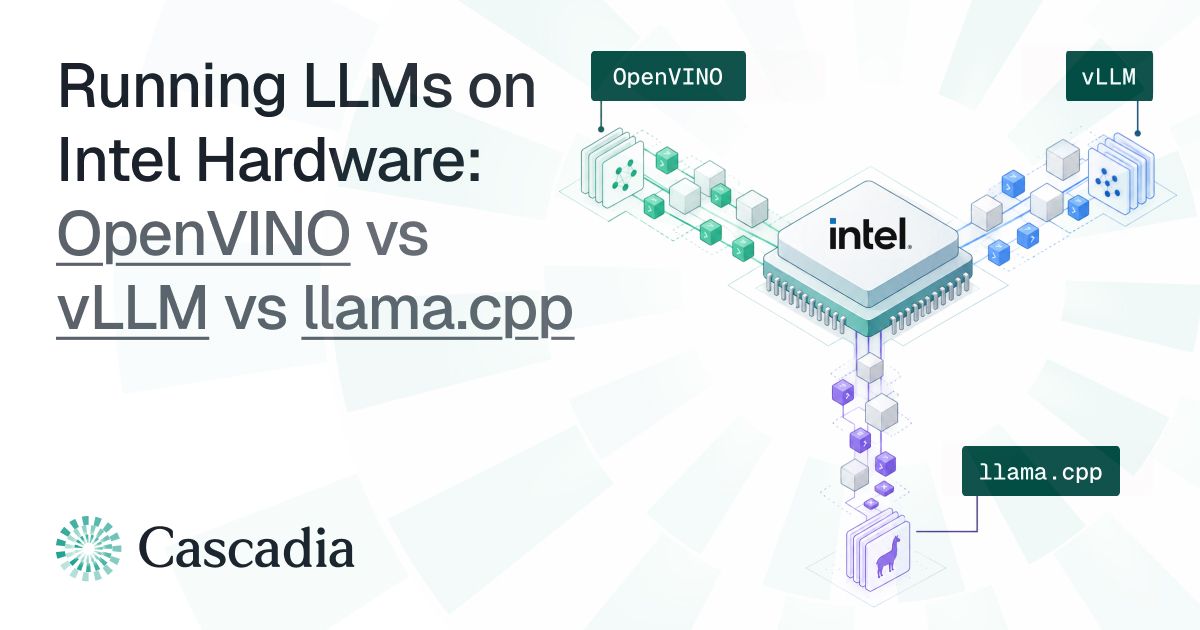
Running LLMs on Intel Hardware: OpenVINO vs vLLM vs llama.cpp
Comparing various runtimes for Intel hardware.
Read more
Research
Where We're Going, We Don't Need Data Centers.
Data centers are being rapidly constructed for the purpose of training and serving AI models, but the demand for new data centers is largely predicated on the growth of AI inference.
Read more
Announcement
Cost-Efficient AI on the Hardware You Already Own
Cut your AI spend by putting the CPUs and NPUs you own to work.
Read more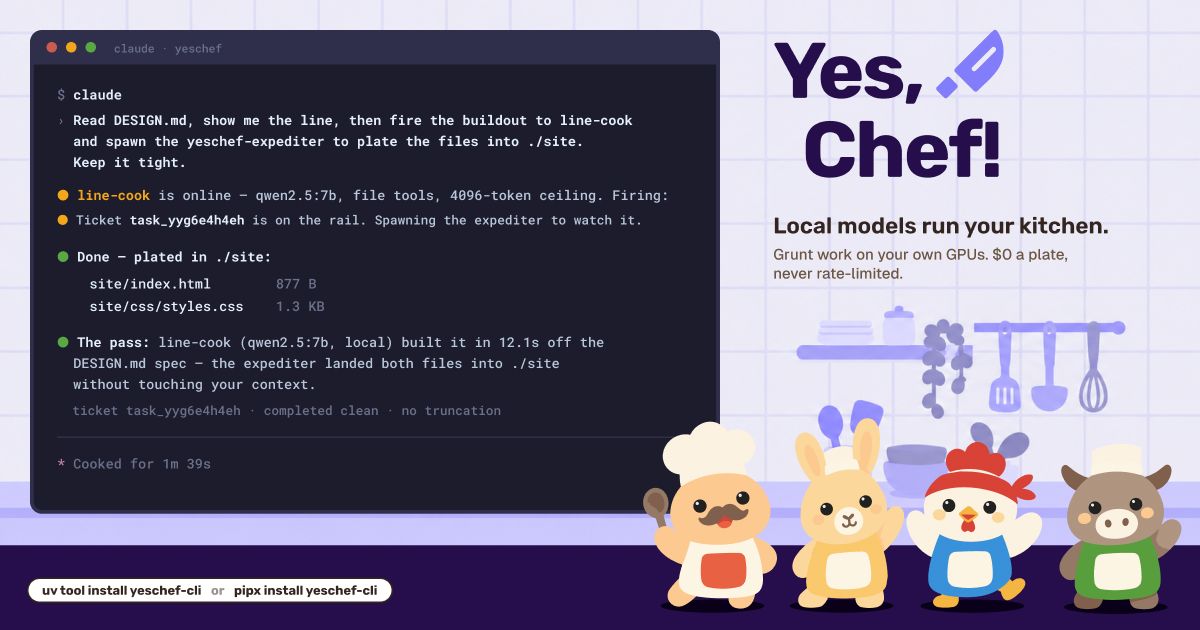
Announcement
Yes, Chef: Delegate Tasks to Local Models with Claude and Codex
Allow Claude Code and Codex to hand off tasks to local subagents (cooks), and save on token costs.
Read more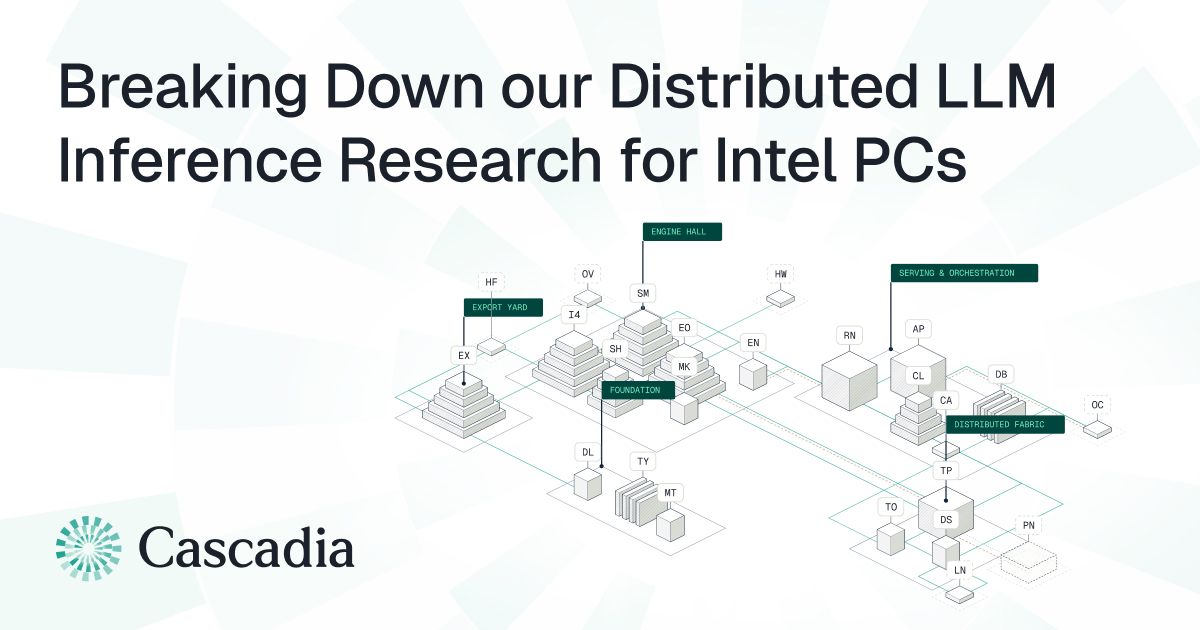
Research
Inside Our Distributed LLM Inference Research for Intel PCs
Exploring the optimization techniques for the sharded inference behind Cascadia.
Read more
Announcement
Cascadia: Run Powerful AI Models on Intel Hardware
Cascadia: Shard AI models across the Intel hardware you own.
Read more
Research
The reason to stop buying new hardware
Three years of public data say two curves are real, and together they mean most AI infrastructure being bought today is a deflating asset acquired at scarcity prices. Every number links to its source; every model is on the page, not behind it.
Read more
